 INDIE / MACHINE
Yumon
Experiments in local models and interactive worlds for Yumon Pet, with training results and implementation notes. 5 posts.
When running small neural language models on local integrated GPUs (iGPUs), standard tokenizer designs create a severe architectural imbalance. A typical Byte-Pair Encoding (BPE) or WordPiece tokenizer exposes a…
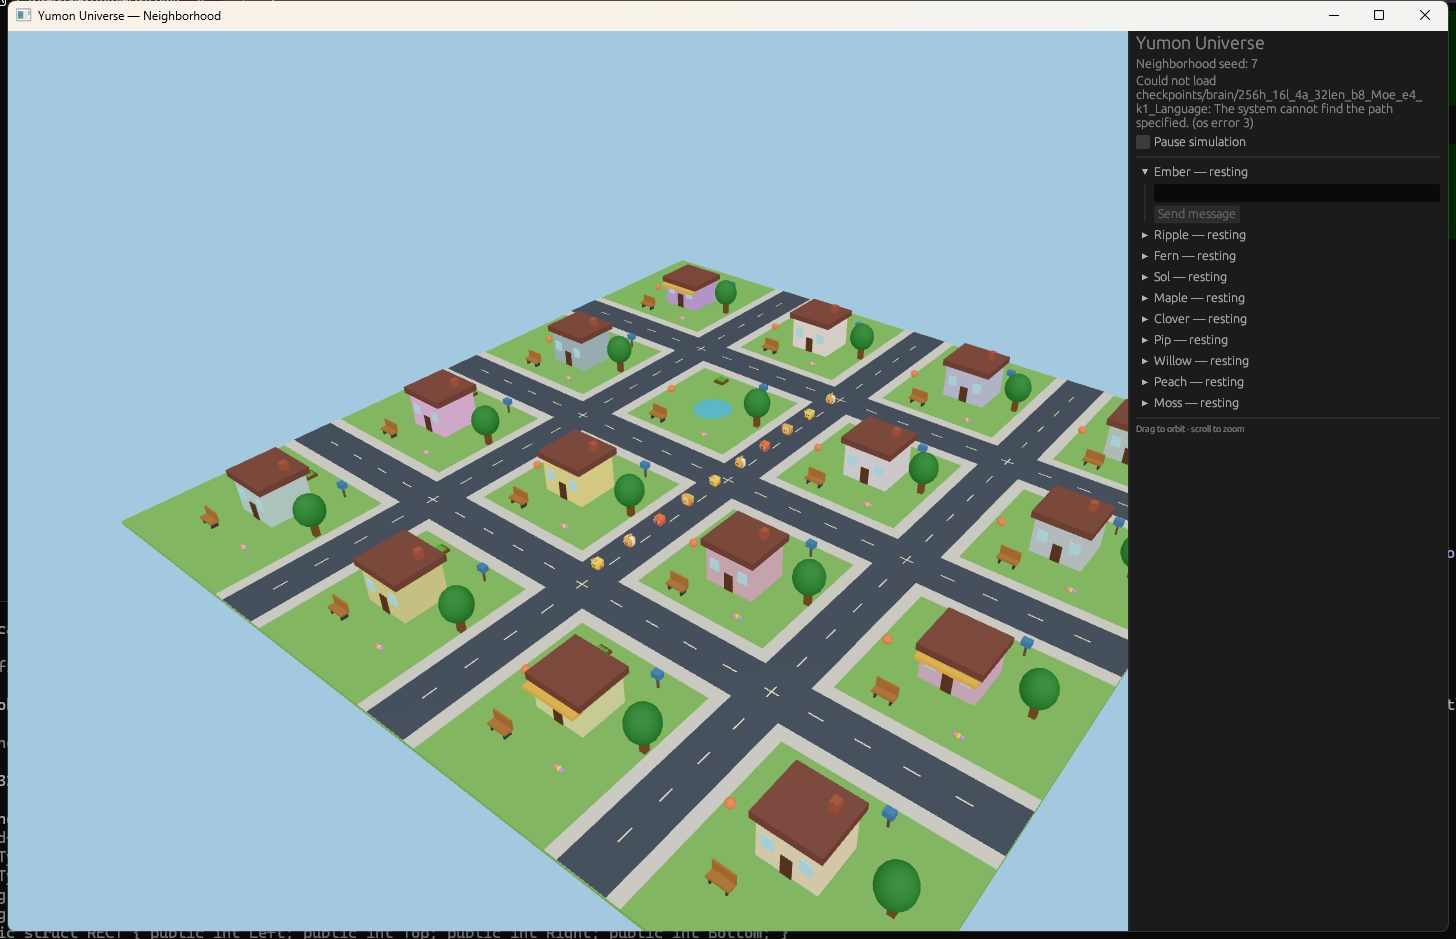
Yumon Universe (src/universe.rs, src/bin/yumon_universe.rs) drops ten Yumons into a seeded procedural world and lets them decide what to do next from a plain-text reply their own checkpoint generates. No prior post has…
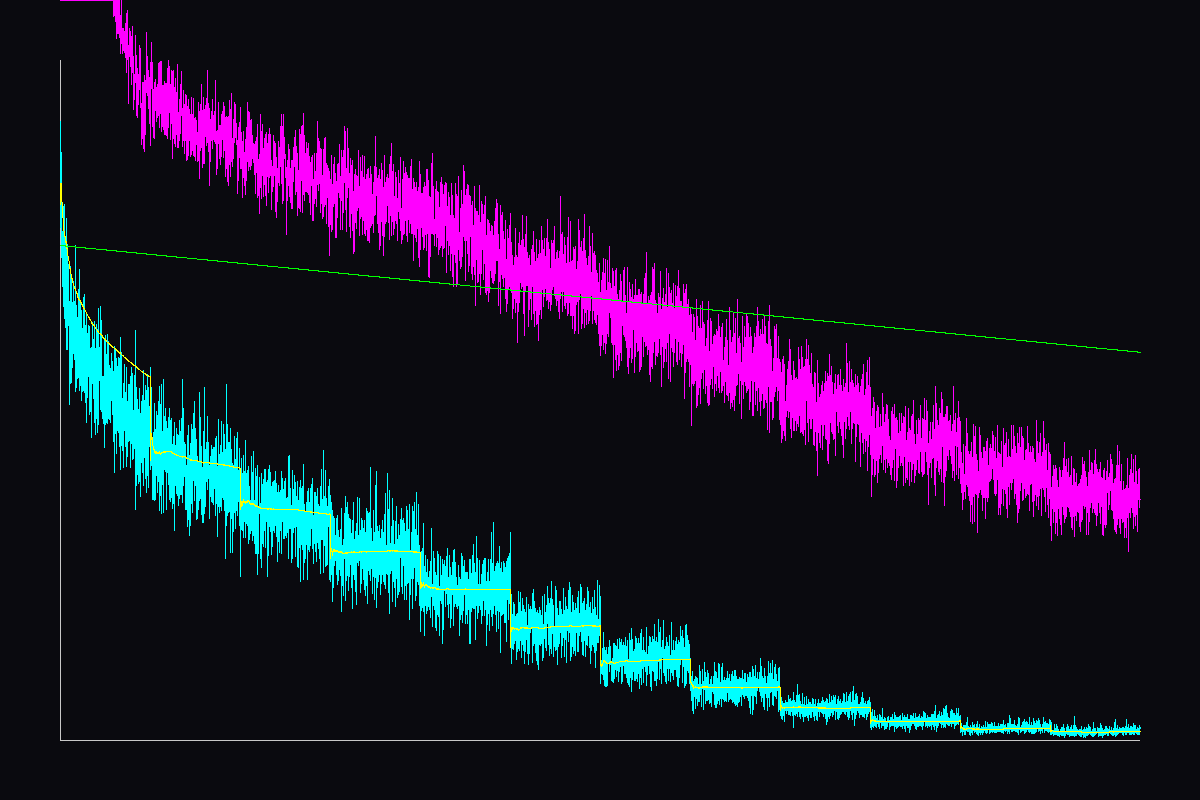
The previous post closed out twelve xLSTM runs with zero checkpoints worth shipping - the lowest-loss one was stuck in an exact repetition loop, and none of the twelve made it to their planned 15 epochs. Same day, the…
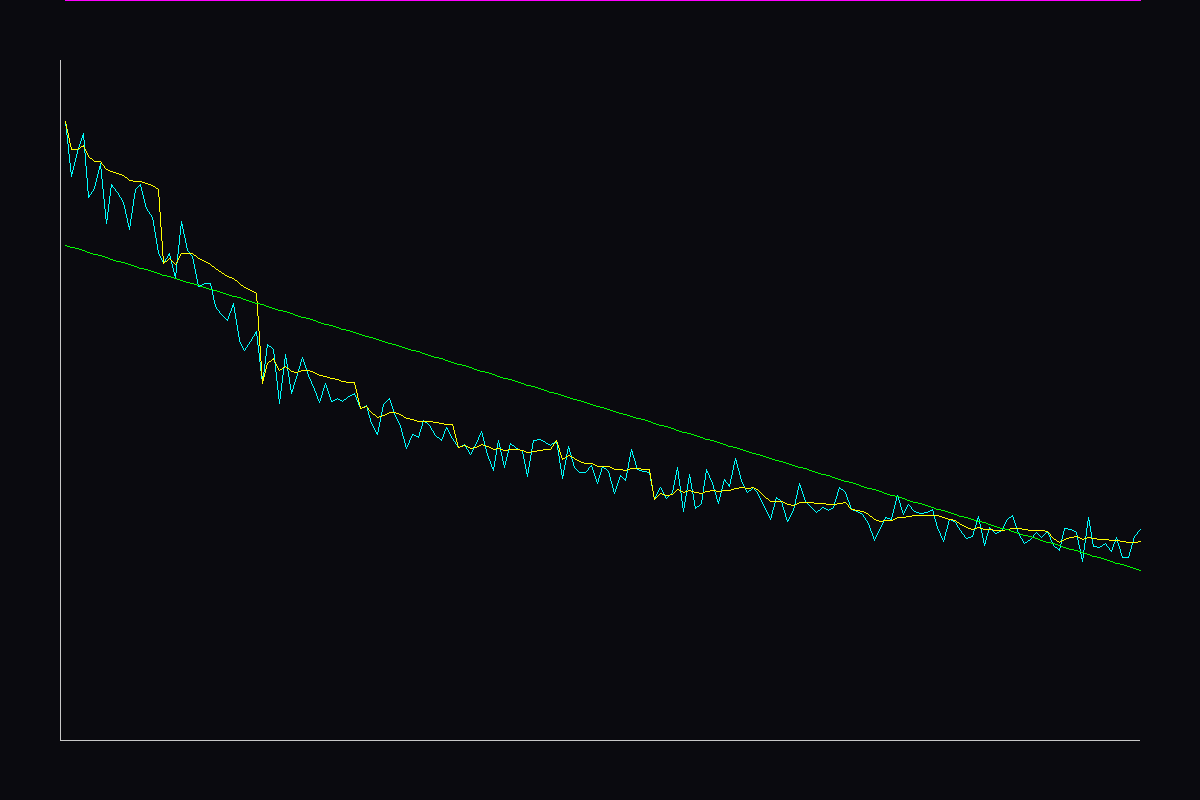
The last Yumon Pet post found that the lowest-loss checkpoint in the repo produced the worst prose of three. That was one architecture (DecoderOnly, plain causal attention) at three sizes. This post is a new…
Yumon Pet trains a small decoder-only transformer from scratch in Rust, using burn for the model and cubecl's Wgpu runtime for the flash-attention kernel. The repo has been through a dozen training runs at different…